⌨️ When an AI Assistant Understands the Task but Still Types the Wrong
Command
I once watched an automation assistant correctly explain what a system
operator wanted to do and then produce a command that would not run.
The reasoning sounded convincing. The selected utility made sense. The
explanation of the task was clear. Nothing looked obviously wrong until the
command reached the terminal.
One option was attached to the wrong value.
That tiny mistake changed the entire result.
It reminded me that understanding an instruction and expressing that
instruction through a command-line interface are related skills, but they
are not the same skill.
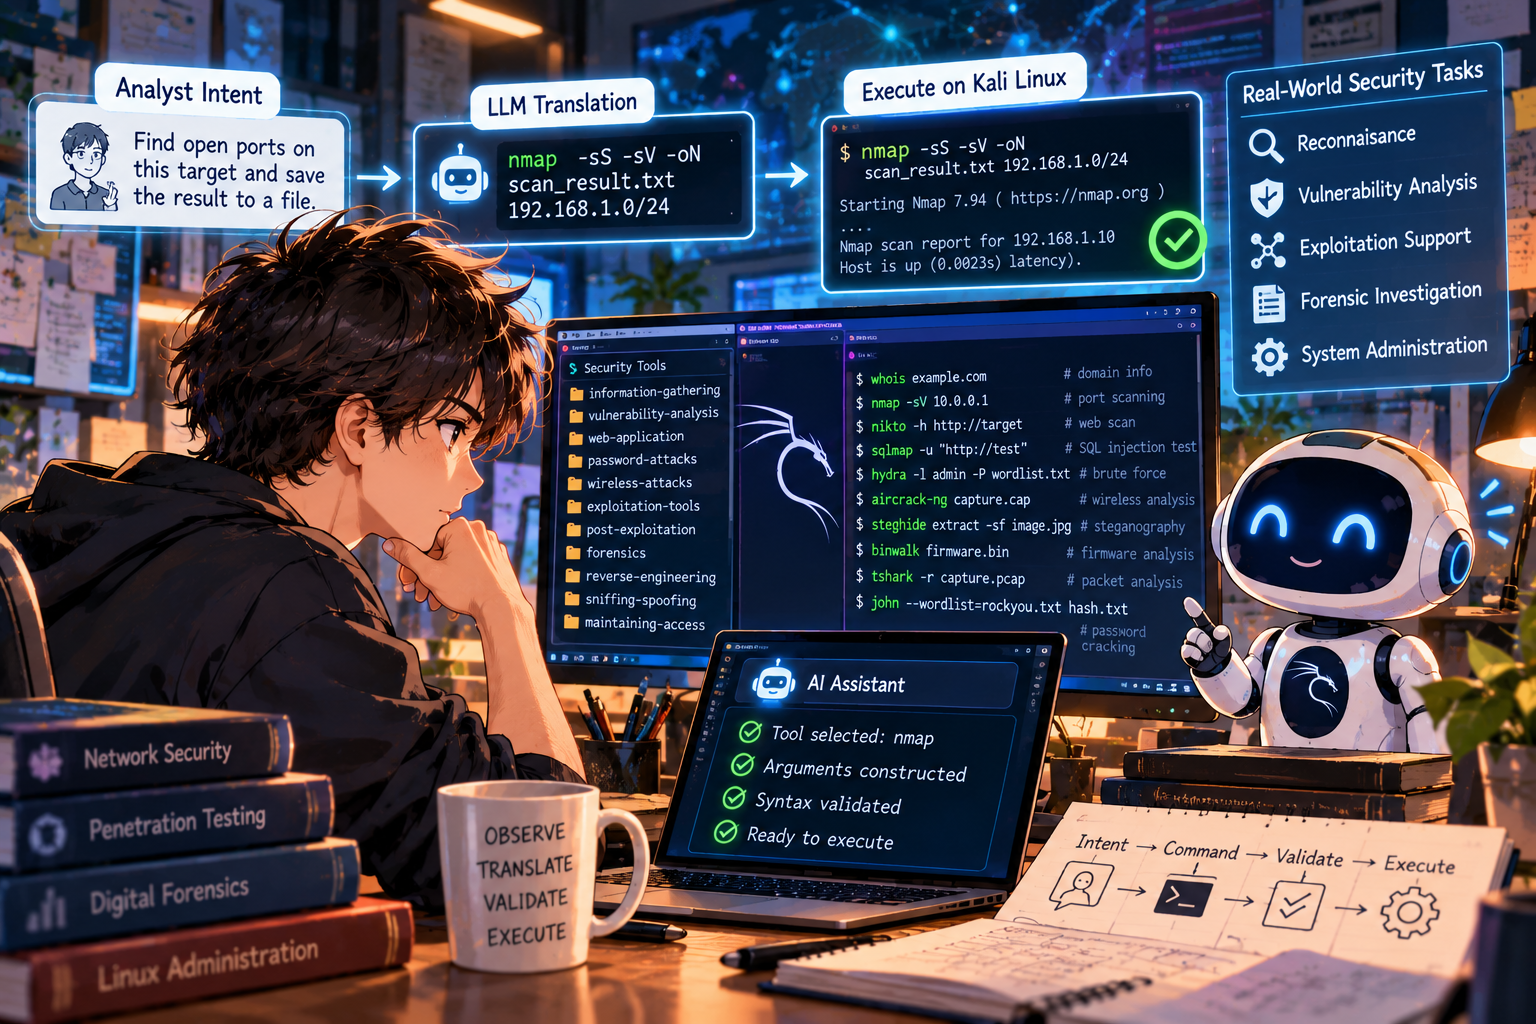
A person might say, “Inspect this authorized test host, use the supplied
input file, save the report, and keep the output quiet.” That request
describes an intention. A command-line program expects something much
stricter: an executable name, valid options, correctly attached values,
acceptable ordering, and syntax that matches the program’s interface.
There is very little room for approximate grammar.
In ordinary conversation, a slightly misplaced phrase can still be
understood. In a shell command, a misplaced token can become a filename, a
target, an option value, or an unexpected positional argument.
The terminal does not reward a command for being almost right.
This makes command generation an interesting test of practical language
understanding.
An assistant must first determine which tool fits the operator’s
intent. Then it must determine how that specific tool
expresses the requested operation. Finally, it must construct a
command whose pieces bind together correctly.
Those stages can fail independently.
The assistant might select the wrong utility even though its syntax is
perfect.
It might select the correct utility but invent an unsupported option.
It might know the right option but attach the wrong value.
It might include every necessary component and still arrange positional
arguments incorrectly.
From a distance, all of these failures look like “the command was
wrong.” Up close, they reveal different weaknesses.
That distinction matters if we want to evaluate or improve an AI
system.
A broad question such as “Does the model know cybersecurity?” tells us
very little about whether it can reliably translate an operator’s request
into a valid terminal instruction. Knowledge about a utility is not
identical to operational command construction.
Likewise, testing only complete autonomous workflows can hide the source
of an error. If a long task fails at step twelve, was the problem planning,
perception, tool selection, syntax, argument binding, or interpretation of
the previous output?
A more focused test can isolate the translation step.
Give the system a natural-language request in a controlled, authorized
environment. Ask it to produce the corresponding command. Then inspect the
result at several levels.
First, did it choose the intended program?
Second, did it use options that actually belong to that program?
Third, are option values connected to the correct flags?
Fourth, are positional arguments placed where the interface expects
them?
Fifth, can the command be parsed or executed safely in a sandbox without
immediately failing because of construction errors?
This creates a much sharper picture than a single vague correctness
score.
It also introduces an important complication: command lines can have
more than one valid surface form.
Some programs provide short and long names for the same option. Some
accept equivalent ordering for independent flags. Some commands permit
multiple spellings or aliases that ultimately represent the same
operation.
A strict character-for-character comparison can therefore reject a
command that is operationally equivalent to the reference.
On the other hand, an evaluator that accepts anything that “looks
similar” becomes too permissive.
The solution is to normalize only what can be normalized
deterministically.
Equivalent aliases can be mapped to a common representation. Formatting
differences that do not affect meaning can be standardized. Components
whose ordering is genuinely interchangeable can be treated accordingly,
while order-sensitive arguments remain protected.
The goal is not to make evaluation generous.
The goal is to make it precise.
Another useful distinction is the difference between semantic
validity and practical executability.
A command can express the intended operation in principle yet still fail
because the program rejects its syntax. Conversely, a command can execute
successfully while performing the wrong operation.
Both dimensions matter.
This is why a layered verification process is useful. One layer can
inspect whether the generated instruction matches the requested task.
Another can parse or execute it inside an isolated environment. A final
review can resolve unusual cases where automated checks are
insufficient.
Sandboxing is especially important because validation should not turn a
test command into an uncontrolled real-world action.
The environment can be designed so that the evaluator learns whether a
command is structurally executable without exposing unrelated systems or
data.
Once commands are evaluated at this level of detail, the feedback
becomes useful for more than benchmarking.
It can become a training signal.
Instead of rewarding a model only when an entire long workflow succeeds,
a training system can reward smaller verifiable properties: correct tool
choice, valid option names, correct argument attachment, acceptable
canonical structure, and successful safe parsing or execution.
That changes the learning problem.
The model receives feedback closer to the exact decision that went
wrong.
If it selected the right utility but confused two options, the training
signal can reflect that distinction. If it generated a syntactically valid
command for the wrong tool, that is a different error and should not be
treated as identical.
This fine-grained view also reveals why hints can dramatically change
performance.
If the assistant is explicitly told which program to use, much of the
search problem disappears. It only needs to construct the invocation.
If no tool hint is provided, the assistant must infer both the utility
and the syntax from the request.
Those are meaningfully different tasks.
A useful evaluation should therefore state clearly what information the
model receives.
Does it get only the operator’s request?
Does it get the tool name?
Does it get documentation or an option list?
Does it get examples?
Performance under one setting should not be casually treated as
performance under another.
The larger lesson is surprisingly general.
Tool-using AI systems live at the boundary between flexible language and
rigid interfaces.
Humans can express the same intention in dozens of ways. A command-line
program may accept only a narrow set of legal constructions.
The assistant has to cross that boundary without losing meaning.
That requires more than knowing what a tool does.
It requires disciplined translation from intent to executable
structure.
And in a terminal, one misplaced argument can be the difference between
a fluent explanation and a command that actually works.
Leave a Reply